State of Microphones?

Several years ago, when I first started on my speech recognition project I was just using a Yeti USB microphone. However, then the Matrix Voice came along, that look like exactly what I wanted so I got one and I have been using it for a couple of years now.

But recently, it seems like the community/the project behind it may be dead or dying. So I’m wondering whether it might be time for a change. I have taken a look around, and I have seen that a few people are using Matrix microphones like me, several people are using ReSpeaker microphones, and some people are using USB microphones.

I was hoping to get opinions from people. Of the products that are available now, what do you think are the best ones and why? I would like to have something that can handle recognition from a distance and in the presence of noise, similar to what the big brand assistants can (Amazon Echo, Google Home, etc.). Having LEDs is nice, but not the most important thing to me.

The Yeti is OK if using win / mac but a lot of the goodies and software are missing on linux.

There are a whole rake of Matrix like microphones that have these arrays that are a whole duplication of worthless ness unless you move up to the higher price USB built DSP models.

One of the biggest problems is noise and array microphone such as respeaker with no beaming algs are just that duplicate omnidirectional mics so noise from all angles is treated equally.
Unidirectional have various polar patterns cardioid / suoer cardioid and its all about how much they reject from the rear and sides.

If you have no algs to create a polar pattern then get a mic with a polar pattern as without they are highly susceptible to noise.
Even mics and packages that come with AEC only cancel what is being played through that capture card / mic.

Budget no DIY prob a cheap soundcard & shotgun mic for pc/camera/phone and on Linux it will be better than your Yeti as the mic has a polar pattern and doesn’t need linux software that doesn’t exist.

Budget and a bit of DIY solder a jumper wire to an unidirectional electret to a couple of $ mic preamp module and a soundcard.

There are some really good mics out there that can hear a mouse fart in Africa from your front room but add noise of HiFi and TV and the voice AI recognition goes to hell.

There is the likes of the BOYA BY-MM1+ & BOYA BY-MM1 which is you do some shopping around there are some very similar China imports with same specs for just over $10 and those if all fails can be used with camera / phone or as a desktop broadcast mic as there ‘shotgun’ nature projects forward and rejects noise from side and rear.
BOYA BY-MM1 is cardioid & BOYA BY-MM1+ is super cardioid which is a polar pattern that just rejects more from side and rear.

Sensitivity isn’t really a matter but -36Db is good but -46Db is equal as your likely to need some form of AGC as sound quickly diminishes through distance and you can only set a mic gain so high that it doesn’t clip @ near where without AGC far the audio amplitude will be very poor.

I am hoping rhasspy will support multiple KWS and use the best KW hit as 2x unidirectional mics can point out at an angle and give both a polar noise rejection and wide area coverage but the only advantage is via placement so that depending where you are noise=rear & voice=front and is just incremental improvement over a single mic.

The commcerail products such as Google Home & Alexa have a clear advantage as the hardware is fixed and if we could hear what they receive we would prob think they are pretty crappy but they do enough to attenuate noise and beamform enough that custom models are made specifically for the hardware platform and the hardware profile is in the model so it works more accurately than many of us can achieve.

I just recorded some samples to highlight the catch-22 of a good microphone and even a cheap sound-card and a basic mic can get reasonable results.
Here though is the UK and behind me is a quite noisy fan heater that if I want far field and to use AGC the AGC will ramp up and play that noise.
I can use basic speex noise-reduction and AGC but that gives artefacts as it is noise-reduction and not removal.

So near=.3m with agc on and NS on
https://drive.google.com/open?id=1zvetgGR7ftyJoHV41fk80gRXLLkXKorI

Turn off NS
https://drive.google.com/open?id=1XYsOqSpHi-9B2HqAxT4IXWIlZmVZZKtM

Far with AGC
https://drive.google.com/open?id=1p2_9BYih4oC905aziNHn7vlh5gURAGVX

Far without AGC
https://drive.google.com/open?id=17TX6bfxVNNWxTRgFyysuf8LSTiUejnSr

The catch-22 for the likes of Amazon & Google is that they could training models for specific hardware setups and even though that may sound bad for recognition they provide perfectly good results.
Rhasspy has all sorts of hardware attached as its open to choice so its models are recorded relatively clean.
The only way to have the magic to do all and create relatively clean voice takes much more hardware than Google or Amazon need as RTX Voice on a high end GPU could provide clean voice against all manners of noise without a hint or at least minimal artefacts.

Prob if we all used the same, we all used Speex then the models could be recorded so and the best Mic would be the one the models where recorded with and algs of use.
Likely a really cheap and simple setup could give excellent results as the models are all recorded with those hardware profiles.

But from hardware to software and models included in that software is all different and mainly expects clean noise free which if you have RTX cash then its quite possible.
At a lower $100 scale the DSP mics are great for far field and beamform but with the introduction of noise it all goes to pot.
So its any mic is a good mic or no mic unless your going to splash the cash on some high end GPU based RTX voice like function depending on what you deem fit for purpose.

There is a lot of stuff with arrays and pixel rings that really is no advantage over any cheap mic as we don’t fixed hardware or the software algs that the big guys have.
Thank you for your very detailed response! I’m not going to lie, much of it goes over my head. Are you aware of any array microphone products/projects which do implement beamforming and things like that? I think that this was part of the promise of products like the Matrix Voice, which didn’t come to be.

USB respeaker but not really a fan.
Anker Powerconf doesn’t like Linux.
Acusis S Linear Microphone Array but a bit pricey

Still all suffer with noise though.

I just recorded some samples to highlight the catch-22 of a good microphone and even a cheap sound-card and a basic mic can get reasonable results.
Here though is the UK and behind me is a quite noisy fan heater that if I want far field and to use AGC the AGC will ramp up and play that noise.
I can use basic speex noise-reduction and AGC but that gives artefacts as it is noise-reduction and not removal.

So near=.3m with agc on and NS on
https://drive.google.com/open?id=1zvetgGR7ftyJoHV41fk80gRXLLkXKorI

Turn off NS
https://drive.google.com/open?id=1XYsOqSpHi-9B2HqAxT4IXWIlZmVZZKtM

Far with AGC
https://drive.google.com/open?id=1p2_9BYih4oC905aziNHn7vlh5gURAGVX

Far without AGC
https://drive.google.com/open?id=17TX6bfxVNNWxTRgFyysuf8LSTiUejnSr

The catch-22 for the likes of Amazon & Google is that they can train models for specific hardware setups and even though that may sound bad for recognition they provide perfectly good results.
Rhasspy has all sorts of hardware attached as its open to choice so its models are recorded relatively clean.
The only way to have the magic to do all and create relatively clean voice takes much more hardware than Google or Amazon need as RTX Voice on a high end GPU could provide clean voice against all manners of noise without a hint or at least minimal artefacts.

Prob if we all used the same, we all used Speex then the models could be recorded so and the best Mic would be the one the models where recorded with and algs of use.
Likely a really cheap and simple setup could give excellent results as the models are all recorded with those hardware profiles.

But from hardware to software and models included in that software is all different and mainly expects clean noise free which if you have RTX cash then its quite possible.
At a lower $100 scale the DSP mics are great for far field and beamform but with the introduction of noise it all goes to pot.
So its any mic is a good mic or no mic unless your going to splash the cash on some high end GPU based RTX voice like function depending on what you deem fit for purpose.

There is a lot of stuff with arrays and pixel rings that really is no advantage over any cheap mic as we don’t have fixed hardware or the software algs that the big guys have.

https://www.digikey.com/en/products/detail/antimatter-research-inc./AR-ACS1/13147322

I see, so I’m understanding correctly, we are essentially “screwed” by the fact that the speech models are hardware agnostic. This may be an advantage for the project, which desires to serve many different pieces of hardware, but a disadvantage if you want absolute best recognition. If I’m looking to have a form factor similar to a device like an Amazon Echo or Google Home in the less than $100 price range, it sounds like there is no advantage to having array microphones versus a simple one or two microphone hat?

If you can train your own KWS & ASR on your hardware with noise profiles…

But yeah you hit the nail on the head as to allow choice of hardware & also software with a collection of 3rd party models it does make things a bit mission impossible unless you provide hardware and environ trained models.

@Light the 1/2 microphone hats are omni directional and at a disadvantage to a simple unidirectional old school electret plugged into a sound card.

The Raspberry Zero Codec is prob best choice as it has a single mems omni onboard but also a stereo 3.5mm and aux in and aux out as you may find without beamforming plugging in a unidirectional is better so its gives choice over a fixed hat.

For me the audio quality that the WM8960 hats give via omni directional mems is actually pretty low quality as they pick up everything that you don’t want as well.

I have a preference of a usb sound card and unidirectional mic as you can also isolate the mic to an extent that is near impossible on a pcb mounted hat.

@sskorol managed to get some of the respeaker freeware working for beamforming, aec, ns

Hmmm. I’m not sure where I should go from here. Perhaps I should provide some context.

As many people have done, I am making a device which can control a device in the home. The major difference is that the device being controlled is a hospital-style bed. My current setup with Rhasspy and a Matrix Voice is “acceptable”. I somewhat frequently get false positives on the wake word and falsely recognized intents. I have not extensively adjusted settings, and I understand that some of these issues may be alleviated. However, my primary reason for starting this thread is concern over longevity, as it appears the Matrix Voice days may be numbered. I believe a directional microphone might not be a good choice because it limits the positioning of the device and the use case itself is not fixed (the speaker might be positioned at various locations around the room). There will always be some noise.

So I’m trying to figure out what my best option might be going forward and I really appreciate your advice so far. I’m not against training my own models, but honestly have no idea where to start with that. I took a look at the Raspberry Zero Codec and it has some attractive features for my purposes. I would like to use a 1.2 W speaker, or a pair of them to reduce dependency on large USB speakers for audio feedback.

I really couldn’t make a recommendation for a hospital style bed.

Guess its just price from then WM8960s start @ $10
Zero Codec $20
Respeaker DSP USB Mic array $65
Acusis S Linear Microphone Array $100

Or got the other way

Just running scared of making any suggestions for ‘Hospital style bed’ so just examples more than suggestions.

Ha. I do have the ability to control it through the Echo, but I’m trying to move away from that because, obviously, it’s not local. I can run all of this on a battery backup so even if Internet or power is lost, it is still good to go.

Don’t worry too much about the hospital style bed. My point was more to illustrate that it’s more like controlling lights in your house, but not something you can typically do with off-the-shelf items, so it’s actually serving a need rather than just being a fun experiment.

I played with both Matrix Voice (ESP32 version) and ReSpeaker Core v2 in a smart home context. The latter gives much better results due to available DSP package from Alango. It’s not perfect, but it’s better than nothing in Matrix.

Note that I don’t use Rhasspy. I use Vosk (https://alphacephei.com/vosk) as ASR and Spacy (https://spacy.io) as NLU engine for my native language + custom sensors firmware.

If you are interested in a websockets server built on top of librespeaker DSP, check my repo: https://github.com/sskorol/respeaker-websockets

Thank you for your reply! So I have taken a further look, and have some follow-up questions for you.

Have you tried using a ReSpeaker Mic Array v2? It claims to do some of the algorithms such as beamforming, noise suppression and AEC on board. I’m also interested in your choice to use a single board solution rather than a Raspberry Pi + voice add-on. Can you discuss the reasons for doing that?

Why did you choose to use Vosk and Spacy over Rhasspy?

does not have beamforming, noise suppression and AEC on board, they do supply librespeaker and @sskorol has done a brilliant job of setting it up which is a 1st as I know.

http://respeaker.io/librespeaker_doc/

Prob Russian lang but will have to ask @sskorol

edit ReSpeaker Core v2 does not the usb does

AEC only cancels what it plays as do most, NS can cause artifacts that can reduce recognition in clean models but the beamforming is pretty reasonable, some say can be a bit hissy @fastjack .

No, I haven’t. It’s a USB mic, so you have to buy an additional hardware to work with it. It’ll be more expensive, consume more power and space. Moreover, there are no benefits in pairing a mic array with other boards just for audio pre-processing. It’ll be a waste of resources. I prefer standalone Alexa-like boards for DSP and streaming to a dedicated server such as one of NVDIA Jetson boards. Assuming you are building a brain for your house, which may potentially include not only ASR/NLU engines, but also a computer vision stuff, it makes more sense to consider more powerful hardware with GPU.

I didn’t even consider Rhasspy seriously. But the main answer is flexibility, accuracy, performance and a great customization. I can raise a good offline ASR server for my language with GPU support in several lines of code. I can train custom NER or classifier the way I want and don’t restrict myself with a rule-based approach. I just like to have a full control over everything in my home. So that’s pretty much the reason.

1 Like

I was just going based off of what the microphone array product page says. Thank you for the clarification on AEC. Still helpful to me, as it my use case has audio feedback, but an important distinction nonetheless.

So if I’m understanding correctly, you are using your ReSpeaker web sockets library as an input to Vosk, but Vosk is running on separate hardware? Is the ReSpeaker Core v2 powerful enough to do Vosk and Spacy on the device? I have no plans for computer vision.

Correct, Vosk/Spacy/mqtt broker and the other stuff is running on Jetson Xavier NX / Nano board (I have both). Respeaker Core v2 has only 1Gb RAM + there’s no CUDA (for decreasing ASR latency). Respeaker board is capable for running only a lightweight processing logic. ASR/NLU is too heavy for it. It’s hard to even program there, as VSCode cpp tools require at least 4Gb RAM. So remote development is very limited. That’s why I just deploy a streaming software there to apply DSP and send pre-processed chunks to ASR server via websockets.

Okay, thank you for explaining that. It’s good to know what the capabilities are of the device are. I’m guessing you have a couple ReSpeakers positioned around the home, all streaming to a single Jetson which is doing the processing? Would it be possible to send audio data over a physical connection such as USB instead? Where can I go to learn more about setting up a speech recognition system using Vosk + Spacy?

Thank you to both you and @rolyan_trauts . I feel like I’m learning a lot of useful information thanks to your explanations.

You might actually not need all that as if you just have simple control then maybe you just need a multiple keyword KWS and some simple logic of your own if functions of control are limited.

We are all different as I found the Nano board quite hard work as it is 2gb but its shared with the GPU unless you get the 4gb and then its not such good value for money.
Also the Nano i didn’t think there was all that much difference with the 0.5 Tops GPU and what I have seen on a Pi4 which guess could have a Coral AI accelerator with is 4 Tops.
I don’t suggest a Coral AI as its very bespoke and unless you run the demo models and need a extremely fast Parrot detector its not much use without a lot of work.

I managed to get a Haswell Nuc for £80 and I like the reuse slant as well and the AVX2 instructions with the clockspeed, 120gb SSD and the 4tops mini pcie £24 parrot detector has a spare slot if I use a USB dongle.

The 1st Gen Intel Core Nucs are approx same as a Pi4 but Haswell generation Nucs can go quite cheap like the D54250WYK I got.
But if you just need simple control then just a KWS means just a Pi3 or Pi4-2gb or you can try the other demo with the Parrot detector which is a voice activated game of snake.

Yes, several Respeakers stream the audio to Jetson board when KWS is triggered.

Well, if you use a USB mic, you can write a streaming code for the board it’s connected to. If it’s RPi 4, you can even run Vosk there. But w/o GPU. So performance won’t be as good as on devices with CUDA.

Vosk has 2 types of models: big (for server, e.g. PC or Jetson-like boards) and small (for RPi or Android/iOS). Big models are heavier in terms of resources consumption, but more accurate. Technically, you can run big models even on RPi 4. But again if performance matters and you want a super responsive ASR, it’s better to run Vosk on boards with GPU.

If you really want to try it, I’d recommend to play with a desktop version first. Just to check the accuracy for your language. You can find docs and a number of examples for different programming languages on their GitHub: https://github.com/alphacep/vosk-api. Note that small models with dynamic graph allows vocabulary adaptation: you can increase the probability of some words’ appearance while transcribing.

In regards to Spacy, I’d agree with @rolyan_trauts that you probably don’t even need this stuff, if you are building something simple. Yes, Spacy definitely gives a good control and flexibility, but as it’s a low level library, it’ll always be a hard path.

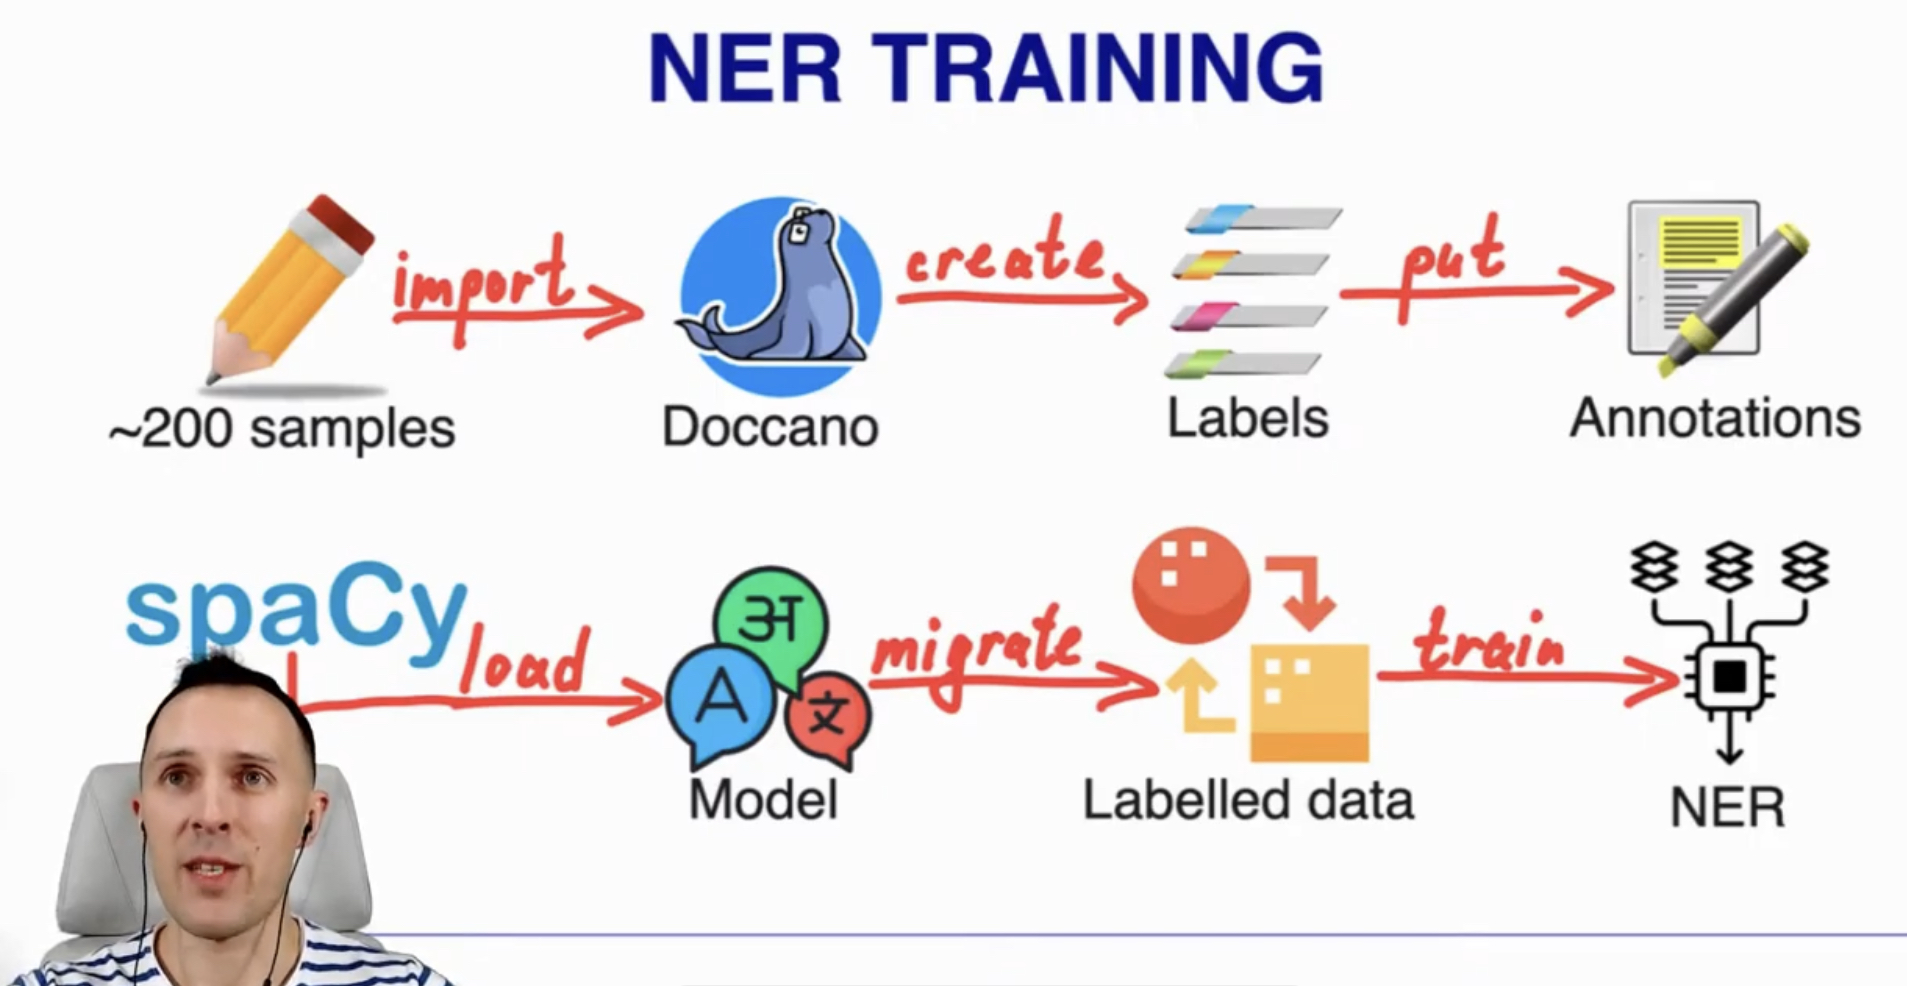
But if you really curious, you can try training a simple NER by example in one of my repos: https://github.com/sskorol/ner-spacy-doccano. The most complicated part is the training data preparation and labelling. Not even complicated but rather boring, as you have to collect about 200 real-life examples (yes, Spacy NER doesn’t require thousands of samples) which might be potentially said by you or the users of your software. Then you should label them via special annotation tool like Doccano or LabelStudio and export for further training in Spacy.

That’s a screenshot of my recent meetup on this topic which describes the process:

Anyway, feel free to ask questions if you want to go this path. But it’s not an easy one.

To talk about training you can need far more than 200 to get really accurate as just more is better with models especially ones of use.
If you want you can have a go with https://github.com/StuartIanNaylor/Dataset-builder which was just to prove that is put behind a web interface training models could be real easy starting with as low as 20 KW samples & !KW.

It has a record.py, split.py and mix.py to create large datasets by augmented a few provided samples automatically. Its not as good as a large set of usage samples but augmenting to make many is a a good enough second.

The you can train the model with https://github.com/StuartIanNaylor/g-kws which is really just the state-of-art Google stuff that I have done a bit of a write up how to install and get going.

You can create a model on a desktop with or without GPU and ship out tflite models to run on a Pi3A+ a single models runs about 20% of a single core on 64bit of RaspiOS its only the training when any extra muscle helps.

Its not application as this is all about voice what voice commands do you want to use? List them or approx the qty and action of the command as that will make things much clearer.

I think the kernel is limited 2 8 devices on raspi OS but cheaP USB soundcards and unidirectional lavaliere mics as with approx 20% usage of a core you can have multiple inputs and multiple KWS and use the best KW hit channel and you only need to train the model once as its just purely directional instances.

Likely for a bed a stereo pair each covering a side or more would work well with what are relatively tiny Lavalier Microphone

There is a shop on ebay with a large range https://www.ebay.co.uk/str/micoutlet/Microphones/_i.html?_storecat=1039746619 but likely shop around and you can get them for less than $5

The unit can go in or under the bad as you just need to position the mics which are tiny.

The main thing with KW is the more unique and phonetically complex the easier or more accurately you will be able to detect. So ‘Raise up’ is better than 2 KW of ‘Raise’ & ‘Up’, ‘Bed Raise Up’ is better than ‘Raise up’ and so on.

There are loads of ways to do this but many usb mics have software that doesn’t run on Linux especially high quality ones such as Blue Yeti.

The quality varies drastically but often purely due to not knowing any better the alsa parameters and mic settings are just pure bad to start with and low volume.

Beamforming and unidirectional are bad expressions as no mic pics up a beam they just have a narrower pickup than from all directions.

http://www.learningaboutelectronics.com/Articles/What-are-cardioid-microphones# even the ‘beamformers’ are just directional cardioids when in use.

Get any mic the cheaper the better and start training with a frame work as you will soon start to learn the pitfalls and how much noise can affect.
Deciding now before you even try anything is likely going to change.

Get a cheap soundcard and a cheap omni or uni directional from ebay or aliexpress just to test some frameworks it will be no worse than the 2 mic hats that for me have extremely bad recording profiles.

Also you never said is this a universal model for many users or custom for a user of choice as universal models need many voice actors and even though we have many ASR datasets word datasets don’t really exist and why often ASR is used for what really is KW capture.

Very interesting. I didn’t mean a USB microphone, I meant streaming the processed audio chunks from a ReSpeaker Core via USB to another device, such as a RPi. Naturally I recognize that (almost) all of the smart home products on the market communicate over Wi-Fi, and do not themselves do speech recognition. My motivation for not depending on a Wi-Fi LAN is simply that the main use case for the device I’m working on is for individuals with a disability (namely myself), so I would like to depend only on having power to the speech recognition device and the bed itself, which can both be accomplished by a UPS in the case of a power outage.

At this point, the argument could be made that the primary method of control would be a local smart assistant, which could be set up the way you describe: ReSpeaker Core streaming over Wi-Fi to a separate server which then streams commands to the individual functional devices. This method would allow for much richer and more accurate recognition as well as being able to control a variety of other devices throughout the home besides just the bed. That approach has value to me.

The secondary method of control would be a simpler and less accurate speech recognition on the bed control device itself. This could be used whenever the primary method was unavailable (in cases with no power or loss of Wi-Fi connection).

This response is really in response to both @sskorol and @rolyan_trauts. To answer @rolyan_trauts question about specific speakers versus universal speakers, I would much rather support universal speakers.

Both of you seem to be either professionals in this field, or at least expert hobbyists, and I really appreciate your help so far. I myself am a professional graphics programmer for video games, so although I have software development experience there is much more that I don’t know about this field than I know.

What I’m gathering from our discussion so far is that I should probably focus on the secondary method of control (because for the time being the primary method can be satisfied using off-the-shelf products until I have time to implement a local solution). Furthermore the secondary method of control can probably consist of a relatively simple and inexpensive two microphone hat, like the IQAudio one mentioned previously, for example, on top of a RPi. At that point, I would just need to settle on some sort of ASR + NLU system, I’m guessing? I would eventually like to have something that supports a custom wakeword and accepts commands given in a natural language format, like “raise the back of the bed up”. However, I have no interest in supporting a wake word chosen by the user at this time. Hopefully that makes sense and you guys can steer me in the right direction.

I forgot to mention, I do currently have a working prototype using Rhasspy -> NODE Red -> my custom control software.

If you want universal speakers then go the ASR which collects spoken phonetics and via a dictionary base and some clever context can predict a word or sentence.
They are prebuilt on universal models often and you are sort of ready to go but can be susceptible to noise. Often though they are recorded ‘clean’.

If you where going to train a custom KWS then you would not have to have a KW but your simple command sentences would be a collection of KWs and likely to have better noise resilience and be more accurate as you can record on device of use.
Each voice actor would have to be recorded though.

The IQaudio has only a single omnidirectional on board mems as its really pointless without DSP beamforming to have multiples to provide a single stream as apart from the time of speed of sound of the distance between them the input will be identical but there will be out of phase latency so why they should nto be summed and why its a bit pointless having more than one unlesss you do have some DSP algs.
It has a stereo 3.5mm mic jack and stereo Aux in like most of the hats it steals your GPIO and doesn’t provide a pass through it does have pads for a SMD header or soldering direct.
Actually the 3.5mm might be mono and its stereo with the other channel being the onboard mic I just have never tested.

Oh, I would like GPIO access, at least via a stacking header. I’m wondering why they sell (or people buy) double microphone or microphone arrays without the various algorithms running to clean up the recordings. I mean, obviously I did because I didn’t know any better.

Unfortunately because they sell respeaker has a whole range of relatively useless that sell quite well.
The ‘maker’ market got profitable and it got lubricated with snakeoil.

I suppose someone was hoping somewhere that the algs might be released but think its unlikely as either you have loads of clock speed or a rtos where extreme close timings can be guaranteed. The Pi is lacking both.
We would of seen at least one manufacturer boast and release software by now as its been a long time gripe but we haven’t and that sort of speaks volumes.

But it goes back to fixed hardware platforms where everything is custom trained for and the relatively false idea you can just cheaply DiY odds and sods and compete with the likes of Google or Amazon.

There a are niches but with mics they are much the same and often the advantages of others are not really worth the price difference.
Like I say it the catch-22 of the bring your own open approach to hardware and also a collection of software.

I was browsing @sskorol github and noticed he does https://github.com/sskorol/matrix-voice-esp32-ws-streamer

Which might be better than some others as quite a few on here know I have a utter hatred of raw wav’s over MQTT but even broadcasting raw wav’s for me seems crazy seeing how 20 years ago the Ipod made a codec of some type sort of mandatory.
ESP32 or over cheap low cost mics that are distributed and you can select the best stream from a array of distributed mics that broadcast from KW to silence or kick.

Maybe he might be interested in getting a CNN running on the ESP and using AMR-WB as a codec as the g-kws has a CNN ready with a MFCC front end with goodies to run TF4MC

Audio “frontend” TensorFlow operations for feature generation

There is the ESP32 Alexa that Atomic made but he used the spectrgram tutorial and also the benchmark dataset Google command set as its deliberately hard with expectations nothing will get 100% as it is a benchmark KWS dataset otherwise its the most lousy trashy piece of work Google have ever released :slight_smile: .

I actually think MFCC is the killer codec as for an ASR its lossless as its what it uses anyway the 16:1 compression can also run through gzip and be absolutely tiny in a similar way Google is boardting about Lyra.

Depending on how comfortable you feel training your own language model you can also look at doing it all in node-red.
I develop and co developed a few speech control related nodes for node-red.
I have had really great experiences using deepspeech recently in my set up. With a domain specific language model/scorer its fast enough to do real time or faster streaming asr on a pi 4.
The good part about deepspeech is that its a lot easier to start training your own language models and add new vocabulary to combine them to a scorer than it is to add vocabulary and train models for kaldi asr (vosk).
You can have a look at this collection of voice related node-red nodes here:

There is also things like a jsgf (the grammar format that is also used as the base for rhasspy rules) permutator which can be used to quickly create a text corpus for language model training that i wrote. This can also be used to create a tagged corpus to do very basic fuzzy intent recognition.

On the microphone side i fully switched to using max9814 electret microphone breakouts connected to a usb soundcard inspired by @rolyan_trauts as i found them much better than the 2mic seeed card or the iqaudio hat. I actually get quite decent range and detection with this set up.

Johannes

Did anyone have a look at Speechbrain as I went on about it but never did give it a try as I think it tries to make Kaldi easier. Its all very new and need to have a look one time.

Yeah I am not really a fan of the IQaudio hat either but as opposed the respeaker its just more flexible with the 3.5mm and aux-in but as it comes with the onboard omnidirectional mems its just 2x the price of the respeaker 2 mic.

I think most of it is those cardioid electrets as they do have reasonable sensitivity and SNR but boy it was many I tested but definitely a preamp with the max9814 especially the one with its own regulator seems the best.

Part of the problem and why I haven’t tested the iqaudio hat that much is the absolute overkill and complexity of there alsamixer config which is super complex and would seem to be undocumented.

The Lavalier into a sound card is just the non DIY to get the advantages of a cardioid that doesn’t cancel background noise it just picks up better from the front and that is really useful and as audio equipment have been used for decades.

From PS3eye to respeaker I have had to repeat time and time gain the secret sauce is the DSP or otherwise you are purchasing PCB mounted mics that are omnidirectional that often take all the GPIO and also near impossible to acoustically isolate.

I presume though because @JGKK is custom training with the hardware of use that actually the accuracy is quite good but likely doesn’t have complete datasets of the hardware of use like the big guys do, but can get very good results.

If I use the term bemused I am sure for some it will bring a grin but yeah I find it completely bemusing that a voice application seems to shy away from initial audio processing and maybe it is so complex or there are conflicting interests and an overestimation of the resolution and results DSP beamforming and Algs can produce.

I can actually beamform with a stereo soundcard and 2x angled cardioid and use the threshold hit of a KWS to select my stream but the project doesn’t have any method to select best KW hit and just uses the 1st in.
USB are really handy as they don’t steal your GPIO and you are not limited to one as with the above and 2x stereo soundcards I can run a single beamformer on a single core of a Pi3-A+ omnidirectional with 4x 90’ cardioid beams as I have a KWS that can run in less than 20% single core load, or at least Google do.

I am just an oddball though as again and again the request for omnidirectional beamforming and when I look around I never see its need apart from the adverts showing how great it is as a conference mic but in use it never seems to be central and often is on a table or shelf plugged in somewhere close to a wall.

Yes, a lot of your speculation about the proliferation of these devices does sound plausible to me. Unfortunately, much of the rest of your message goes completely over my head. :slight_smile: At this point I’m not seeing a particular reason to stick with the Matrix product line, as it seems to be in the very least in hibernation and by @sskorol’s analysis inferior to the ReSpeaker Core, anyway.

Thank you for your input. I was actually looking at moving away from using node-RED. It was expedient to set up my test case, but felt a bit unnecessary in the long run considering it is ultimately driving an executable written in C++.

I honestly have no idea about training my own language model. I’m not against trying it, I just don’t really know where to begin.

Thank you for suggesting the microphones. Which USB soundcard did you choose?

Yeah, I don’t have a need for beamforming, as far as I know. Noise suppression and accurate recognition from a moderate distance are much more usable to me.

Noise suppresion prob not as software NS can leave artefacts as its sounds like your going to use a universal non custom trained which will of been trained without NS so prob just go without.

You can try a version of NS that comes with Speexdsp and for some reason the asound2-plugins are lagging behind revision on debian but you can do an update here.

Sounds like you have what you need with what you currently have setup as after you do go round the houses you tend to come back to any mic can do or will at least have to.

Honestly I still feel a bit like my head is underwater, I’ve gotten tons of great information from several people, but with my lack of experience it’s hard to sift through it all and act on it. Previously you mentioned a preference for a unidirectional microphone connected to a USB soundcard. Can you elaborate on specific microphones and soundcards? What kind of software are you using in your setups?

Just plain rhasspy but a cheapo USB card and unidirectional mic.

I use a BOYA BY-MM1 for testing and stuff as use it also as a desktop mic and its on a little mini camera tripod so its just handy.

Like all china product can be a bit hit and miss as sometimes you never know what is inside as if Intel chipset you lucked out as they are pretty bad.

The white ones seem to be relatively consistently ID 1b3f:2008 Generalplus Technology Inc.
The black ones which build wise are a bit better quality seem to more often be the bad intel chipset than the above.

You always know what your getting with these as its a CM108 and they can not hide that as its not in a case.

For no solder jobs starting with cheap but cardioid (unidirectional) cardioid means heart shape and the bottom of the heart is the front of the pickup pattern.
So very cheap not that sensitive as it works backwards as a theoretical no loss mic has a sensitivity of 0db

-52dB ± 2dB 3.5mm TRS (tip ring sleve) 3 pole 3.5mm jack plug (phones are 4 and the contacts are in a diff place, you can get convertors but hey)

The sensitivity on this looks really great but it a TRRS 4 pole that is for a phone as an example

But you can get adapters make sure it says for microphone as the tip & ring are stereo out

It does get quite confusing as often labelled wrong and often ignore the description and go off what you are looking at.

To the Boya I use

Or what looks the same unbranded but they are half mics and bigger than lavalieres where the mount is the camera type which for me works well as have a mini desk tripod.

Or you can go full DiY and get a preamp

Make a 3.5mm lead and connect to a usb sound card

Electrets you can buy from me as it will save you buying x25 but for price and sensitivity + SNR they seem to be the best and you can try to see if you can get elsewhere but seems quite hardwork so why I bunged a few up on ebay.

Its just 2 wires to the preamp board and no more components

Thank you, this gives me a bunch of stuff to try. I will hopefully report back after I’ve had a chance to try some of this stuff.

1 Like

The White ID 1b3f:2008 Generalplus Technology Inc. seem to have the best hardware AGC and gain over any and should say they are worth a punt as even if you get a wrong one they are very cheap and its not a major dent to source elsewhere.

Should say I often scour ebay abd aliexpress but PiHut should guarantee its the correct type.

Yeah, I think I located the same one over at Adafruit here in the States.

1 Like

If lsusb reports 1b3f:2008 Generalplus Technology that is the one they are not quietest but the range of the AGC is really good and negates the need for a preamp.
The CM108 prob gives a cleaner signal but the lower levels make a preamp module preferential for far field but they do add an extra step that allows you to get more gain a bit more cleanly.

If you want a cheap hub then my 1st buy worked out really well but stay clear of these.

I thought hey that is just like the 1st one but also with a header array of all the usb pins which is handy but for some reason seem to disconnect and freeze on the Pi3A+ I have tested on.

Really cheap though and seem to work well which was my 1st buy of a cheap ‘board’ hub.
So blue seems OK and purple maybe stay clear but like all these modules they do seem to vary and maybe I was just unlucky.

1 Like

Yeah, I plan to check when they arrive.

PS I gave a bum steer as not a fan of the respeaker USB so my memory is foggy at best.
Its not a beamformer that has to be applied by software its just AEC + AGC.

No worries. I just received the USB soundcard and electret microphone breakout board, but haven’t had a chance to test either of them.

1 Like

Just to plug in with no DiY I did check out one of these and very similar results to my boya but much smaller and cheaper.

Nice, that looks like a pretty convenient option. My friend is helping me assemble the microphone breakout board now, but I may consider something like this if we run into problems.

If you have the max9814 run the gain with the jumper at low or medium at most high is definitely over optimistic and noisy.
I use the gnd from the 3.5mm jack and then 5v to board 5v.
Electret -+ just needs to go to -+ on the input and that should be your lot.

But yeah if you run into trouble the above will just plugin has a little mini gooseneck and actually is hard to tell the difference to my £20 Boya.

Okay, thanks. My friend and I usually only meet once a week, so perhaps we will get to try it soon.