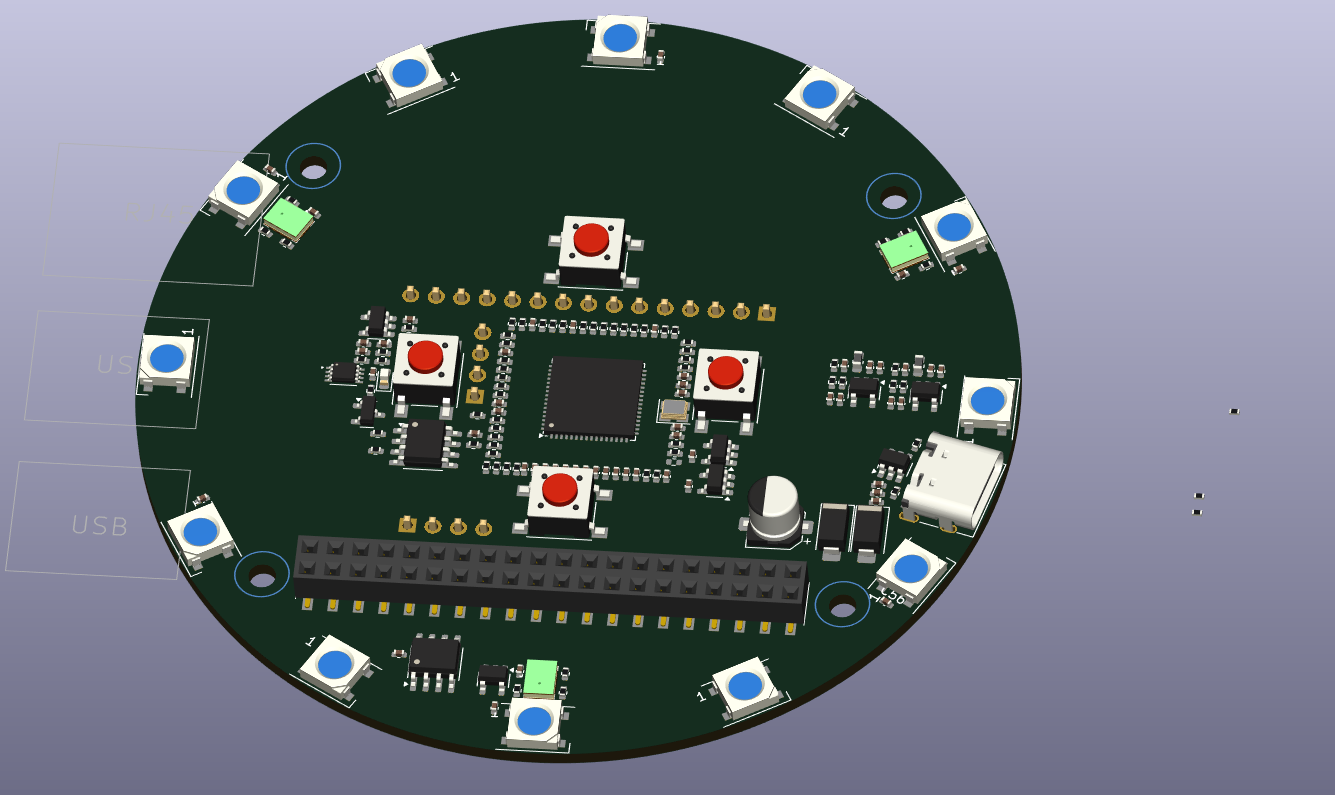
I have been designing a DSP based 3x mic array and speaker for a ESP32-S3, however the DSP in question could be connected to a Raspberry Pi or over USB
Hi @Alextrical! I saw your post over in the HA forums. I’m definitely interested
I know the Lyra-T used the ZL38063, but I’m curious if you’ve considered other chips. The XMOS XU316, for example, seems to be capable of similar things (echo cancellation, noise suppression) but also some machine learning applications like wake word detection.
The XU316 is a bit more expensive ($11.20 USD vs. $8.20 USD), but it’s essentially a 2x 8-core 500Mhz multi-core processors each with 512 Kb of RAM that can run TensorflowLite micro
On the other end, I see the ESP32-S3-BOX-3 with the ES7210 for audio input and the ES8311 for audio output. These are very cheap, but also push much of the audio processing onto the ESP32-S3 itself. This seems like a downside, but maybe it would be more cost effective to just add a second ESP32-S3 at around $2.50 USD to do the audio processing?
Some important things that have happened recently to make the “dual ESP32-S3 with no dedicated audio chip” idea less crazy:
microWakeWord runs well on the S3, and there will be even faster models released in the coming weeks (averaging 3.7 ms to process 20 ms of audio)
I’ve gotten the noise suppressor and automatic gain controller from speexdsp running on the S3. It averages 9 ms per 20 ms of audio to do clean up, but what’s nice is this only has to run after the wake word is detected and until the voice command stops. When microWakeWord is running, it just needs to update its noise estimator which takes ~1 ms / 20 ms of audio.
The last hurdle will be to see if the speexdsp echo canceller can also run on the S3. This is where I expect the most trouble because it needs to run at the same time as microWakeWord. If both of them can run in less than 20 ms for 20 ms of audio, though, we’re good (assuming there is a second S3 to do all of the ESPHome stuff).
Glad to see that the project is getting some notice
I went with the ZL38063 because it has support in the Espressif ADF, and as a result be easy for the projects using it such as Willow or ESPHome to incorporate it, with little additional coding overhead to implement. I don’t like the ES7210 ES8311 combo, as you said its putting all the processing on the ESP32-S3 to work out. Intriguing to use a Dual ESP32-S3 setup though, i did wonder if it could be done, but hadn’t seen it in any forum posts
The XMOS lineup really are amazing chips, even for $12usd. The problem I would have is figuring out is if the community would be willing and able to support it in software, as there is little available hardware I’ve seen using that chip
For what its worth, it sounds like you are the guy to talk to about in regards to the hardware you want to really synergize with the self hosted assistant projects.
I will take a look into the XMOS chip, that could be the basis for an amazing core if it can offload the tricky audio processing to allow us to get a device that can work as well as the Amazon Echo Dot v3, at the same time as allowing the use of an self hosted open source system.
Do you believe that the ESP32-S3 (and hopefully never version soon) is the best path for the community to currently peruse, over for example a RPi Zero 2W, or USB DSP connected to a central server running Docker?
I’ve been evaluating ADF for a satellite running ESPHome, and it’s not been great so far. Running the examples on the Korvo and Lyra-T boards has been fine, even the S3-BOXs. But trying to use ADF within ESPHome has been an uphill battle that I’ve lost weeks to so far.
Espressif’s examples seem to assume that they’re the only thing running on the device, and that you can happily patch FreeRTOS. Neither of these assumptions hold with ESPhome On top of that, while ADF does a great job at audio processing, much of the code is pre-compiled binary blobs that Espressif provides. I believe the open source voice community can and will do better if given the opportunity.
I share this concern, but I am happy at least that XMOS has open sourced their code for voice and many of their libraries. I have a dev board and, while the tooling can be intimidating, it is only a little harder to get going than IDF/ADF.
If we can come up with some way to flash the XMOS chip from the ESP32-S3, we could even deliver firmware updates via ESPHome. Maybe with enough effort, ESPHome could even build XMOS firmware alongside ESP firmware.
I do because the S3 (and whatever comes next) clearly have enough power to the do wake word detection and audio clean up without needing to constantly stream audio. What is lacking right now, though, is a demonstration that all of these can work well and at the same time on an S3-based satellite:
Wake word detection
Noise cancellation and auto gain control
Echo cancellation
Media playback (from a central server)
A current limitation of ESPHome with IDF/ADF prevents simultaneous audio recording and playback (though you can do this via the Arduino framework). Once that’s solved, we will be able to see if there’s enough CPU to do all 4 items.
I watched the Year of the Voice in Home assistant with intrigue, and it was amazing to see how much it evolved over that time, unfortunately during that time I had a few too many prior commitments (renovating a home, and a full time job)
Though the software has come on leaps and bounds, i also agree that the hardware is still falling short on what i think could make it a true competitor to the big 2 brands.
The Espressif dev kits are great starting points, but they should be seen as such, a place to build upon, and they don’t have to optimise their code if they dedicate an entire chip to one process.
I think the ZL38063 has potential to be a good chip, but finding out that the configuration software is locked behind a wall, and apparently poor customer service for small ‘businesses’/startups, isn’t ideal.
[quote=“synesthesiam, post:5, topic:4941”]
I have a dev board
[/quote] Assuming thats the XK-EVK-XU316 or XK-AUDIO-316-MC-AB they are some rather nice pieces of kit.
Assuming that the 316 can do everything that the 216 does, I would hope a core schematic we could leverage would be the XMOS XK-USB-MIC-UF216
Have you had any luck so far with getting your dev kit to work for Audio In and Out simultaneously?
That’s definitely possible, we technically don’t need the external Flash chip to store the boot image for the XU316, we can use the ESP32 to hand the data to it at boot. See section 9.3 of the datasheet, we can set the XU316 to a SPI Slave for boot, and then clock the boot image in from the ESP32. also see the Forum post or we can hold the XU316 in reset, and update its external SPI Flash
At this stage, seeing the potential the XU316 has, I’m quite tempted to rebuild the project around it at the core. Especially seeing that it can handle a ludicrous amount of MEMS Mics in an array, and has capacity for language models.
If you are able to help on the software side of things, I’m happy to pump some money into this OSHW project to get it available for purchase to the public, probably a small (UK based) run initially (Still aiming for ~£30-40 for the populated PCBs), but we shall see how much demand there is and go from there (hopefully you believe there is demand)
Likewise, It would be great to see that those 4 pillars of Software are able to run at the same time (and ideally process audio in real time)
So as a sanity check, as it seems you are the developer that I’ve been searching for, what would be your ideal currently released hardware to take the satellite speaker to the next step of its evolution?
I’m guessing the following:
XMOS XU316 (Would you need external LPDDR?)
ESP32-S3 (would a N16R8 be enough, or do you need a N16R16V)
Firmware update capabilities for the XU316 from the ESP32-S3
at least 3 MEMS MIC’s (is more better? we could go to 7)
12+ Neopixels for easy visual feedback
Hardware Mute, with no Software control (Using a buffer to block data from the MICS, or cutting power)
Exposed available GPIO for end user add-on development
The XU316 shouldn’t need any memory, though that would certainly make the device more capable
The ESP32-S3 needs at least 8MB of PSRAM, preferably 16 MB (I believe this is what the S3-BOX has)
Firmware update capabilities likely via a UART or I2C connection
At least 2 MEMS mics - I don’t know enough to know if 3+ will really make a difference
Neopixels yes, but I’m not sure of the arrangement. I always liked the look of the Mycroft Mark I with the LEDs making a face
Hardware mute definitely – just be careful how you do this. Mycroft had a problem when they cut power, and I can’t remember how they fixed it.
Lots of GPIO, both from the ESP32-S3 and the XMOS.
Something you didn’t touch on is audio output. Personally, I think a 3.5mm jack is good enough but others really want a built-in speaker. Mycroft had a powerful amp in the Mark II, but that required a 12V power supply then. In either case, the audio out needs to flow through the XMOS chip to make echo cancellation work.
It looks expandable, so maybe an unpopulated BGA placement on the board would allow flexibility at manufacture time (when an inclined individual gets it Fabbed or we have a run made)
ESP32-S3 Wrover N16R16v modules can be sourced (not that common, but I’ve got a couple on order) Its also possible to add larger PSRAM or Flash chips if needed, I’ve seen up to 128mb as an option
It’s possible to set the XU316 to slave SPI mode, and pump the boot image into it from the ESP32, so the ESP32 has full control and is effectively the data store, it also helps reduces part count
At the back of my mind I’m not sure if I can shake the desire have 3+, to be able to detect the direction of intent from 360 and display it back on the LED ring
I would be aiming for the formfactor of the Echo Dot V3, to be able to make use of the mounting ecosystem, Circular is a pretty easy choice, though we could add a couple of dots in the centre to make a smile too
I’m guessing that they initially went with the data sheet implied method of cutting the power, the other option is to use a tri state buffer to effectively sever the data link, from the return data, or possibly the clock line
Agreed, it would allow development of currently unimagined devices, especially useful for the ESPHome ecosystem
For audio I would be looking to have a 3.5mm jack and a onboard mono amplifier. at 5v we can get around 3-5W of power out of the speaker, if we want that to be more reasonable (10-20W) we would need to go the 12V route. We should be able to make the device able to run on a range of voltages, from 5v to 12V+, by utilising buck regulators. That would allow us to (with the correct component choice) have an audio amp that can work on 5v to give 3-5W audio output, or a higher power audio output, if the PSU is changed to a PD supply that can output 12V.
We could utilise USB-C PD to allow negotiation of the voltage delivered, as to that being a PHY connected via the ESP32 to alter, or a dedicated chip that is strapped to request 12V
Agreed that the DSP needs to be core to the audio output loop
I believe the initial device, I will get the schematic and Fabb-ed, will be based around the ZL38063 DSP, the core reason for this, is that there is initial support in the ESP-ADF and would be of use to a few different Voice assistant communities initially (ESPHome/here and Willow).
Progress of the (ESP32-S3 with ZL38063 DSP) project can be seen on GitHub (Still early drafting of the PCB layout, and checking over component nets, though it will continue to be improved over the next few weeks)
I’m also coming around to this idea, it would allow for more compute to be available to process the Audio input, and be able to leverage the existing projects that can play back audio. Would this be a preferable pathway for you to use for development? The biggest worry I can see would be would be a degraded end user experience at initial setup, but this could likely be negated by improved responsiveness under normal working conditions. (It may even be possible to connect the two ESP32-s3’s together via UART to communicate settings for eventual easier user setup)
I’m still finding it hard to see the best path to try for the initial hardware design between the following:
Single ESP32-S3 with a ZL38063 for offloading AEC, NS, BF, AGC functions, though its locked behind a NDA wall, and closed source blobs
Single ESP32-S3 with the XU316, seems like a really capable chip, and it has a community based around it
Dual ESP32-S3 or ESP32 + ESP32-S3: Using one chip to handle the ES8311 functions, and the other for ES7210, but having a audio link between to two for allowing AEC calculations.
Gah… Is the Dual ESP32-S3 the best choice? Maybe codenaming the project Duo or Duet? I’m not liking how easily I’m being swayed between all 3 options. How do you feel about the options outlined above?
Nabu Casa will likely go with the XU316 option for our own satellite hardware given the cost/performance trade-offs, so that may also influence your decision. The XMOS software is mostly open, but of course the algorithms themselves are not
I’ve done some testing with the Speex AEC and while it’s better than I expected, it does require tuning some parameters for the room size, etc. I expect the WebRTC AEC to be better, but porting that to the ESP is going to take more time.
The ZL38063 seems like a very capable chip. I need to pull out my Lyra-T board and record some samples to test the AEC and NS. Do you happen to have any samples where you’re recording and playing audio out of the same device? I’d like to put together a small collection of samples from these devices in a few conditions with me speaking at a comfortable volume. These would all be done at near (< 1m), far (~3m), and very far (4-5m+) distances:
No noise
A fan close to the microphone or machine humming
Music playing from the device with and without vocals
I think you might find its < 0.3 near field like a broadcast mic, < 1m close field and far field is < 3m.
I don’t think the likes of Google & Amazon devices specs go above 3m.
They will work further than that depending on how loud you yell, but I don’t think they spec or try to certify further than 3m.
With Speex there is the tail and filter size but really its the latency of the device, as when the mic is on the speaker (satelite) there is little distance at 343m/s to account for.
I would expect that would likely be the best path to choose once the software support for that DSP is added to the ESP32 ecosystem by the community.
Its a same there aren’t really many good choices for a open source algorithm as of yet, though it may be that once there is enough public contact with the chips that it may be developed?
Unfortunately not, I attempted to replace the ESP32 with a ESP32-S3 N16V8 and it now won’t get past the bootloader (and haven’t had the free time to work out why and Fix)
The development of the LibreTalk Wave is continuing slowly, its been tricky to find the free time to work on this over the last week. but the top board is now populated and being traced out. I’m still also getting used to KiCAD and having to make a large amount of custom footprints too. (EasyEDA really is easy in comparison, mostly due to a more complete library)
I’m also fighting feature creep on the project, and figuring out how to simplify fabrication for cost reduction (dual layer PCB, single sided PCBA)
Current feature creep is having the Wave’s top PCB being able to work stand alone via a USB-C connector by utilising an external Flash IC for firmware.
The board to board interconnect is being worked to be pin compatible with the Raspberry Pi header, so that it should work as a RPi HAT
After I’m happy with that, the main board for the ESP32-S3 and sub board for the 3.5mm audio output, Amp and USB-C power delivery
Just hack out and broadcast the x2 split BSS sources to a websockets server, or output them as stereo, to know then you need to do a binaural KWS and have a good idea what you are recieving.
Use the x2 ESP32-S3-BOX as you have the github of the working code so hack that out than building up from fresh.
On Arm based boards we already have algs and filters, just needs to setup, but unfortunately implementing Whisper entered dev into a catch-22.
Whisper is trained on near and close speech datasets and it becomes very good with moderate levels of noise and RIR (Room impulse response) [the mixture of with direct sound, early reflections and the late reverberation tail that the distance from the mic will give in a rooms geometry].
It gets very confused when you do DSP and filter noise and RIRs and was a great ready made stop gap, for systems that lacked any form of DSP/Filter.
Now it acts as a blocker to the introduction of DSP/Filter as a rather huge and cumbersome model that needs to be finetuned with a dataset of the DSP to be implemented.
I think the community is very much Chicken and Egg, if there are no consumer/hackable products containing an XMOS chip, there will be little to no exposure, and as a result no knowledge base.
I’m sure if Espressif hadn’t made their chips so cheap and powerful, we would be using some very different chips now.
PlatformIO is a nice platform to develop with, its a standard that works across a lot of different IOT devices, though I thought it still could use the Espressif IDF
e.g.
I think you can use the IDF but that doesn’t bring in the ADF.
If you want to compile from the github with the esp32-s3-box then with the IDF&ADF there are instructions and examples how-to.
How to run with PlatformIO and compile the exp32-s3-box I don’t know as never used and there are no instructions and examples how-to or if the ADF is supported.
There are no consumer/hackable XMOS as many of the libs are behind a paywall. Purchasing libs because you can not find opensource DSP for microcontroller will not change that.
Its sort of strange as the ESP32-S3 with the esspressif libs was forwarded as a way of having low cost ‘Ears/Satelite’ as Pi3/Pi4 and above can start to accumulate cost.
It does have free DSP but the KWS for custom KW is behind a training paywall as each KW has to be trained and the Wakeword is a closed blob from Esspressif but free.
We actually didn’t need DSP as even though a blob its avail free, what was needed was a KWS and we lacked any good datasets to do that.
Esspressif now have ways to create a KW much more quickly and have dropped the price of custom KW. Until a ‘OK Nabu’ or whatever you would of been stuck with ‘Hi Esp’.
Its not just DSP that is needed for ‘Ears/satelite’ as without a KWS it will have to broadcast 24/7/365 the mic input to a server KWS/ASR.
That is just not good as the KWS should ‘hear’ the KW and broadcast for only that command sentence.
That can already been done on Pi boards and Esspressif if the ‘HiESP’ KW is given and the I2S stream then forwarded by websockets.
I never liked the Esspressif KWS as its heavily quantised to run a binaural KWS.
Likely after hacking out the rest of ESP32-S3-Box a better KWS that is opensource could of replaced the Esspressif one.
The Xmos is a expensive microcontroller that will add more cost to buy in the DSP libs and you still then have to create a KWS, because as far as I know they don’t have a KW service. They may have code that you can buy in again.
The idea to hack out the unnessacary from the esp32-s3-box to just mics, adc and esp32-s3 on a small dev board was to give the option of a low cost dev-kit to make satelite, ears or whatever you want to call it.
Higher cost Pi based arm solutions with the respeaker 2mic or USB soundcards is already possible and the community has documented this many times, but the problem now is Whisper an ASR without a training framework or datasets.
To continue with the design of a Satellite Speaker, the design using a ZL38063 has made some progress.
The top board has been layed out on a 88mm Diameter, with 12x Neopixels, 3Mics, 4 buttons (One for HW Mute)
Board to Board interconnect should be compatible with the RPi header
When using via RPi or USB-C, a 3.5mm audio out can be populated
Cost of manufacturing has been optimised, by using only SMD parts, and single sided Assembly
I will start work on the middle board over the next week, that will contain the ESP32-S3 module and it’s support components
What are you thinking would be your use case’s ideal hardware?
I believe you are looking to have multiple audio pickup devices per room, and wanting the hardware to be minimal cost.
From what you have told me previously I believe the following:
ESP32-S3
ES7243E or ES7210 ADC
Dual mic (I’m guessing you don’t want all 3/4)
USB-C 5V power + data to the ESP
no hardware mute?
no buttons?
maybe some PMOD connectors
If that’s the case, I could make up a Schematic and PCB design based on the ESP32-S3-Box-Lite
Its only the esp32-s3 that has the vector instructions that make it capable.
Dual mic and doesn’t have to be mems.
Its any quadcore ADC but the ones as mentioned from the box-examples have ready to go examples.
No buttons, no pmod but dev kit like so its choice what is added than potential obselete.
Lilygo do an amazingly compact esp32-s3 dev kit T7 S3 – LILYGO® so the increase insize the adc and fpc connector would provide, which is also pretty tiny.
We are still stuck though as likely Whisper will reject the DSP we provide unless finetuned.
I only have a RTX3050 which if fine is a tad slow for training a KWS, but have nothing near the gear required to finetune whisper.
As said I could already use a dual mic on USB or the respeaker 2mic but the use of Whisper that unless finetuned for the DSP of use it doesn’t work well, in fact it might not work at all.
Fine tuning Whisper-large-v2 model requires ~24GB of GPU VRAM which currently a RTX3090 is likely the only option.
I dunno if the framework/finetuning allows multiple GPU’s as often they work in parallel each with own copy in memory.
I would make sure you can get the x2 I2S streams from the Espressif BSS and that you can finetune as you now hit another problem of augmenting a dataset.
Likely why Arm Based algs in the long run are better as we can just run on a bigger computer than have the resources to do the same with a microcontroller.
We the Box Lite doesn’t have the AEC feedback and is only using a dual channel ADC, a ES7243E chip that’s around $0.40 (Note it’s a ADC not a DSP)
What mics would you want? MEMS or the capsule mics used in toys and such? MEMS are useful as they are pick and place, so assembly is cheaper.
For software at the moment, not something I’m currently getting into, I’m hoping to get that and feedback from those currently developing the systems
An ARM CPU with an entire os on a SD card seems overkill for a wireless mic, especially when the end user will never perform a safe shut down
I would expect such a basic device to be sub £10 for a wireless mic module. I would still make sure GPIO was exposed, as there is a Lot of demand for that to be exposed from the users I have talked to. And for the cost of PCB space for an unpopulated header, why not.
Lots of people want tonnes of sensors, so this is a good compromise, for near free, if the MCU has enough capacity to compile them in at a later date, and up the the end user to design whatever addons they may desire (at least PMOD is a nice enough standard to follow)
As for the use of a FPC for the Mics, that will add a lot of unnecessary cost to production. If we alwant a device to be cheap, we need low part count, pick and place compatible and single sided PCBA
Mems or Electret as they are called doesn’t matter.
Do it but if all your work proves fruitless then at least others did say.
That we can already purchase in ready-made hardware likely for less than you have estimated.
Personally I prefer the RadxaZero3 as it does beat a Pi4 for some ML.
A bit more at OKdo ROCK ZERO 3W 1GB with Wi-Fi/BLE without GPIO - OKdo but it has the Ooomph to cope with Python like implementations.
Then use a stereo USB sound card with the Max9814 as from use really like the analogue AGC it has https://www.aliexpress.com/item/32864107454.html and a cable.
Have as many as you wish be it Pi or MiniPC.
Like the example I sent that could be not much more than the T7 S3 – LILYGO® as one set of I2S pins is in use.
If you want to copy the onboard designs then do, as said people did say otherwise.
Though if a project is effectively a stripped down ESP32 S3 BOX Lite, that would already have support wouldn’t it?
Nice, so it’s possible to get a WiFi dual mic setup, only needing an external PSU/phone charger, for under £10? I would be interested in the breakdown of parts for that setup.
The ES7243E that the ESP32 Box lite had had AGC, I’m guessing you didn’t like it?
Assuming that the training for the STT has been trained against a ESP32-S3 Box 3, wouldn’t copying it’s mic array setup be the best option to be as compatible as possible, without any re training?
No as what they did is hack out the DSP and Espressif KWS.
As far as I am aware it got converted into a single mic 24/7 websockets broadcast.
I wouldn’t do the Lite but the full with AEC as the cost diff is minimal really.
It would just have a 3rd input to the AEC that a ESP-Squeezelite could connect to…
That is presuming you can get a small batch order done and shipped for under £10 that works…
I always wondered why Esspressif dropped the AEC to a 2 channel, if I remember rightly its controlled by the S3 and is a ADC with several gain settings?
I have forgot now, so have no idea but the quad with AEC and a gain selectable preamp would be cool. Going with the Esspressif design is prob easiest, for me not having a satelite with a mic sat on a speaker means AEC is less of an issue and the ‘Lite’ could be used.
The esp32-s3=box had a x2 mic board seperate to the main pcb, only thing stange is the mic spacing, which is less than I would choose, but copy if using there blob.
I sent you a esp32-s3-box the orig and the Lite, I would experiment with what you have before you proceed.
Welp, yeah that’s a show stopper for that ADC then. The quad ADC is the better choice then
Should be least enough to get a couple of stereo 3.5mm jacks, and pass through the signal to allow for AEC to the spare 2 analogue channels (or maybe merge into 1)
Time will tell, but it’s likely £10 a device, and something that I may be able to persuade some stockists to sell, if it’s fit for purpose & enough interest
Agreed, so far out of the DSP’s and ADC’s I’ve used, the best one was the ZL38063 on a ESP32 Wrover, hence my choice on using that chip initially.
It’s truly hard to test all possible choices and options without spending a load of cash on development. I was hoping to be able to outsource some of the choices to the community’s knowledge
There is a really good application note by Invensense all about basic beamforming
Really its you input frequency that sets how much sample resolution.
Speed of sound = 343,000 mm/s divide by 48khz (common sampling freq)
Gives 7.14583mm per sample, so really you want to be a multiple of that.
I have used 71.4583mm even if it is pushing into aliasing territory.
I have forgot the input freq Esspressif use, it could be 16Khz which gives 21.4375mm per sample
That looks like I nice piece of reading material, currently above my understanding, so will read over it a few times until it starts to sink in. Spacing the mics at a multiple of that formula should be something I can aim towards. (I will check the sampling frequency later when I’m home, and use the formula provided to set the distance multipler) I’m guessing this still stands true for triangular arrays.
No I guess a triangular array is a combination of both broadside and endfire.
Delay Sum is very simple basic beamforming and just putting multiple mics on a board without the science & DSP means nothing really apart from a PCB with multiple mics.
This has been problem with the respeaker range of Pi hats from Quad to to 6 mic which are practically useless due to lack of DSP and tech expertease with software other than a multi channel mic.
Sort of similar to Matrix Voice where they all lacked the DSP and likely the computational level to do so.
There are various algs such as GCC_Phat that can approximate the time difference between x2 signals or multiple inputs.
Each microphone added increases sensitivity but also increases computation to 2^ and simple delay-sum only provide modest levels of attentuation and likely more powerful and better DSP should be used.
Hmm, well that’s a shame. So I take it that the main issue is that there is little to no community expertise to make those algorithms run on the ESP32 itself, or if we go to a DSP, any open source algorithm’s that are capable of doing the job.
I was hoping that the respeaker had community support for 360 beamforming using the 6 mics, having them as 3 stereo channels only somewhat sucks.
I am guessing there isn’t as audio DSP is a very different arena than basic control.
You can just judge on what has been provided and direction things took and what is currently missing.
Even then for what you are asking 360 beamforming is really for conference speaker phone and sit table central with many speakers.
Smart speakers by nature of being a speaker are generally directional.
It’s quite a different ball game when looking at the specifications of what is being used in there. An entire android based device, with 512mb of ram, and a dual core Arm CPU. It’s amazing that an ESP32 can even compete, though also rather telling when Amazon, with it’s race to the bottom with manufacturing costs isn’t using a Espressif chip
Yeah likely quite a powerful CPU guessing maybe A75 cores and likely because as I have noticed with tensorflow multiple threads provides diminishing results (2 threads optimal). Also I think A75 had the Arm8.2 mat/mul instructions that make the A76 Pi5 quite a ML monster (still prefer the [RK3588] similar price near half the wattage) (https://www.aliexpress.com/item/1005004941882246.html)
An esp32-S3 doesn’t need to compete if your only providing KWS and local DSP.
That is why the satelite model is such a crass attempt at cloning consumer e-waste.
You take the ‘Ears’ out of the likes of Alexa and have a single shared brain applying further function and DSP, whilst its impossible to compete with a makers build satelite and stupid to even try when its not needed.
The engineering in the latest Nest and Echo units is tremendous and no wonder Mycroft was such a flop.
Currently 24/7/365 broadcast always on mics is not a good idea for privacy or wifi bandwidth as you start to add rooms,
You can make things easier for yourself with opensource and not stick your microphones right on top of your speakers and take a lateral look at what modern home automation should be without cloning current commercial gadgets.
You have a ESP32-S3-Box & ESP32-S3Box-Lite and you just need to hack out so you have the x2 BSS I2S streams or anyone with a bit more C/C++ knowledge that it should be possible.
They are declared and C/C++ being pointers and own memory constructs it should be so, but I am a complete noob with C/C++ who is surprised how lacking we are in this area of embedded DSP…
Really its dependent on someone to actually guide a development and start collating datasets of use KW and command sentences with a community opt-in.
You can not bring your own to the party, as what is needed is a highly developed system of either a single hardware/dsp chain or a couple of choices that would use different models.
You can split devices into specific function and share central cost and not follow Amazons costly mistake.
You can use less performent dsp and filters if you train an ASR to accept it.
You can even have 2stage KWS that stops 24/7/365 broadcast that the 2nd filters the 1st stage false positives.
Just getting started looking into voice assist, but would like to know why nobody seems to be working with the ESP32-LyraTD-DSPG? It seems to fit a lot of the criteria, ESP based, DSP, Audio Amp, Audio Codec, 3 mics, LEDs and buttons. I figure I’m missing something obvious.
Its a really nice board, though I believe the issue for this community is the lack of the ESP32-S3 using PSRAM. I tried swapping the module over for a S3, but it isn’t able to get out of boot loader mode.
OK, I’m confused. Expressif docs show the lyratd-dspg uses a esp-wrover-b that has 8MB of PSRAM. Is the problem that there is no support for the wrover-b? What about the wrover-e which seems to the newest version?
I don’t think its got anything to do with psram as far as I know they all support.
I can not remember if the esp32-s3-box is 8 or 16 MB.
Basically its price as its £50 dev kit before even being boxed and offloads the DSP to a chip but is still not capable of running a KWS of reasonable accuracy due to the limitations of the esp32 base chip.
ESP32-S3 has pref due to its LX7 vector instructions and for optimised ML it can be 10x faster than a esp32 and even then that is basic KWS.
You have to setup each chip with a menu-config like interface and declare its capabilities, the esp32 is a Tensilica Xtensa 32-bit LX6 whilst the esp32-s3 is a LX7 and likely have different boot and op codes which the compiler with the right declarations will choose…
They are $45 on mouser, what’s cheaper? Its problem seems to be a weak processor. What else is available now? Seems like a lot of people are working on prototypes or making videos with parts that are always out of stock or no longer available. The dspg seems to be close to perfect apart from the processor, instead of starting from scratch is there a reason the dspg hardware can’t be reused with a different none esp processor.
The Cortex A55 supposed little cores with the newer Arm v8.2 Mat/Mull vector instructions for much ML run faster than bigger core A73 (Pi 4).
You can use a Pi Zero2 but dropping to a A53 at slower clock than a Pi3 as stock seems no longer a problem as it was. £14.40
incl. VAT
They are general purpose maker friendly SBC using embedded linux and all the same tools and libs Linux does so for opensource on github to ML frameworks it just all works and much is already known.
The custom DSP chips require closed source licensing and dev on closed sourced dev tools to be released as a product. esp-va-sdk/board_support_pkgs/lyratd_dspg/dspg_fw/docs/license.pdf at master · kedars/esp-va-sdk · GitHub
Likely you could supply synthetic KW datasets but will likely effect accuracy by as much as 10%, guessing the may not have KWS like the few opensource ones being used that have been chosen to work well with synthetic (TTS output data).
Its so bad that there is still no option for collecting KW as an opt-in with Rhasspy or HA and a priority years ago.
Custom vendor hardware means you get locked in with vendor firmware and guess that is another reason why, as its a fast changing arena.
There have been various options avail for a few years so dunno why the procrastination, often the initial dsp dev kit can be a considerable purchase.


 On top of that, while ADF does a great job at audio processing, much of the code is pre-compiled binary blobs that Espressif provides. I believe the open source voice community can and will do better if given the opportunity.